Natural-language search preserves shopper intent; keyword search reduces it to matching terms. Credit: Generated for Simlir
The short answer
Keyword search matches terms. Natural language product search tries to preserve the shopper’s need, constraints and context, then returns products in a structured form that can still be filtered and compared. Neither replaces the other. Keyword search is precise and cheap when the shopper already knows the product name. Natural language retrieval earns its cost when the request describes a situation rather than an item — and the strongest systems use both, with hard constraints as filters and soft constraints in the query.
How keyword search works, and where it is genuinely good
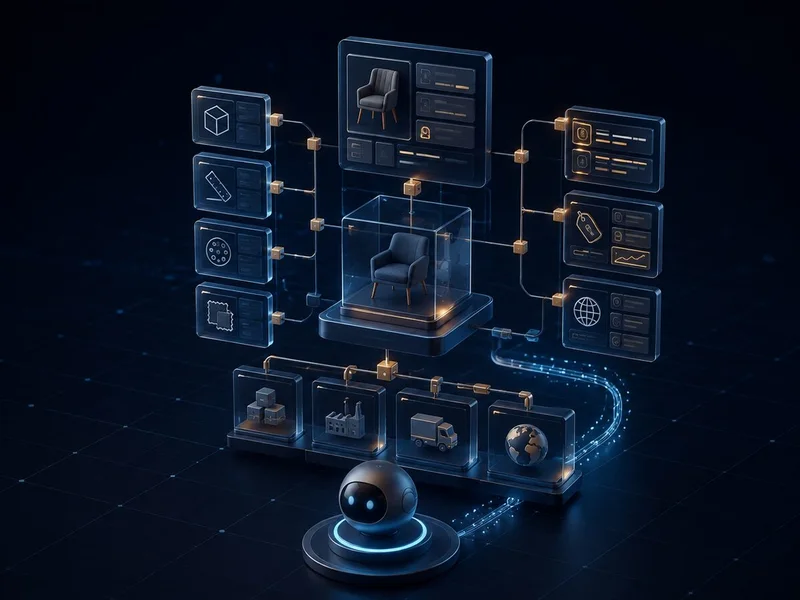
A seven-stage architecture for shopping assistant search: intent, retrieval, structured records, provenance, comparison, MCP or REST access, and failure testing.
Classic product search tokenises a query, matches tokens against indexed fields, and ranks by a term-weighting scheme — more weight for rare terms, adjustments for field importance and document length. Modern implementations add synonym dictionaries, spelling correction, stemming and learned re-ranking, but the underlying commitment is the same:
the query is a set of terms, and relevance is a function of term overlap
.
This is not a legacy approach to be apologised for. It is excellent at what it does:
Known-item lookup. A shopper typing an exact product name wants that product, and term matching finds it faster and more cheaply than anything else.
Predictability. The same query returns the same results, and when it does not, you can usually explain why.
Debuggability. Poor results can be traced to a missing synonym or a field weight, and fixed by someone without a machine learning background.
Cost. Cheap to run at very high volume.
The limitation is specific rather than general. Keyword search fails when the words the shopper used do not appear in the product data. “Quiet” is not in the specification; 42 dB is. “Good for a small kitchen” is not a field; width: 45 cm is. Synonym lists patch individual cases, but they scale linearly with the vocabulary shoppers use, which is unbounded.
What natural language product search adds
Semantic retrieval represents the query and the products in a shared space where proximity reflects meaning rather than shared characters. In practice, three things change.
Vocabulary stops mattering
“Trainers for flat feet”, “running shoes with arch support” and “stability running shoes” converge on the same neighbourhood without anyone maintaining a synonym list.
Context survives
“For an open-plan flat” is not noise to be stripped. It carries a real implication about noise level that a term matcher cannot use.
Multi-constraint requests hold together
“A birthday present for someone who bakes, under £40” is one coherent request rather than four disconnected tokens.
Output stays structured
The important part. Meaning-based retrieval does not have to mean prose output. Results come back as records with identifiers, specifications and prices.
That fourth point is what separates a semantic product search from a chatbot. simlir returns semantically ranked products as structured records with a relevance_score — cosine similarity between 0 and 1 — so you can still sort, filter, compare and explain afterwards.
The most common mistake when adopting semantic search is to put everything into the query string. Some constraints are not soft, and treating them as soft produces results that are plausible and wrong.
Constraint
Nature
Where it belongs
“under £500”
Hard, numeric
max_price — a £520 product is not a near miss, it is out of budget
“Bosch”
Hard, categorical
brand — when the shopper means only Bosch
“dishwashers”
Hard, structural
category — prevents drift into adjacent product types
“quiet”
Soft, qualitative
Query text — then verify against spec after retrieval
“for an open-plan flat”
Context
Query text — it explains the soft constraint and helps you justify the choice
“good reviews”
Soft, derived
Neither — apply as a post-retrieval rule on review_score and review_count
The rule that holds up: anything a shopper would be annoyed to see violated is a filter. Everything else is query text. Nobody is pleased to be shown a £520 product after saying “under £500”, however relevant it is on every other dimension.
The same need, expressed two ways
Take a shopper who needs a dishwasher for a small open-plan flat and does not want to hear it running.
Keyword route
The shopper must first translate their need into the system’s vocabulary: dishwasher, then facet by width < 60cm, then by noise < 45dB, then sort by price. Works well — if the shopper already knows that “quiet” means roughly 45 dB, that slimline means 45 cm, and that both facets exist. Most shoppers know none of this.
Natural language route
q=quiet slimline dishwasher for an open-plan flat plus max_price=500 and gl=gb. The shopper expresses the need; the hard bound stays a filter. Candidates come back ranked, and each record carries the noise and width figures so your application can verify the soft constraint rather than trusting it.
The second route only works because the response is structured. Retrieval gets you a plausible candidate set; the spec object is what lets you check that “quiet” was actually satisfied and drop the ones that were merely nearby in vector space.
product object (abridged)
{
  "id": "a1b2c3d4-e5f6-7890-abcd-ef1234567890",
  "brand": "Optimum Nutrition",
  "category": "protein powder",
  "gtin": "5060245603478",
  "title": "Optimum Nutrition Gold Standard Whey Protein Powder",
  "product_description": "Premium whey protein powder with 24g protein per serving...",
  "key_selling_points": ["24g protein per serving", "5.5g BCAAs", "Informed Sport certified"],
  "spec": {
    "protein_per_serving": "24g",
    "servings": "29",
    "calories_per_serving": 120,
    "flavour": "Double Rich Chocolate"
  },
  "image_url": "https://images.optimumnutrition.co.uk/whey-front.jpg",
  "model_number": "GS100W-2270G-DRC",
  "retailer_sku": "ON-2270G-GB",
  "review_score": 4.8,
  "review_count": 20,
  "price": {
    "amount": 29.99,
    "currency": "GBP",
    "retailer": "Holland & Barrett",
    "as_of": "2026-04-07"
  },
  "links": {
    "retailer": "https://www.hollandandbarrett.com/shop/product/..."
  },
  "market": "gb",
  "relevance_score": 0.923
}
Relevance, explainability and structured output
Semantic retrieval is often assumed to be less explainable than term matching. That is true of the ranking step and false of the system as a whole — provided the output is structured.
Ranking is opaque, but checkable. You cannot read a cosine similarity the way you can read a term-frequency explanation. But you can verify the result against the record: did this product actually meet the constraint?
Explanation lives in the fields, not the score. “42 dB, 45 cm wide, £449 at this retailer as of 7 April” is a better justification than any relevance number, and it is what a shopper wants to see.
Deterministic post-processing restores control. Retrieve a wider candidate set, apply your own filters and scoring on named fields, and you get semantic recall with rules you can test.
Two contract details that shape this in practice: relevance_score appears only on /v1/search results and is not comparable to the visual_similarity_score from image search; and limit is a ceiling rather than a promise, because a post-search sanity filter can remove obvious product-type mismatches. Read meta.count rather than assuming a full page.
Failure cases on both sides
Failure
Keyword
Natural language
Vocabulary mismatch
Common Returns nothing when the shopper's words are absent from the data
Rare Meaning is preserved across wording
Exact model number
Excellent
Weaker Use exact lookup instead — 1 credit, no ranking ambiguity
Plausible but wrong
Rare Mismatches are obvious
Real risk Nearby in meaning, wrong in fact — verify against spec
Numeric bounds
Exact
Unreliable Use min_price and max_price
Negation (“not leather”)
Poor
Poor Handle explicitly as an exclusion rule
Debugging a bad result
Traceable
Harder Requires an evaluation set rather than inspection
Cost per query
Very low
2 credits Cache UUIDs and re-fetch at 1
The row worth dwelling on is “plausible but wrong”. It is the characteristic failure of semantic systems and the reason post-retrieval verification is not optional. A term matcher that fails returns nothing, which is annoying but honest. A semantic system that fails returns something confident and adjacent, which is worse.
A decision guide
If your shoppers mostly…
Use
Type exact product names
Keyword search, with exact identifier lookup where you hold identifiers
Arrive with a GTIN, MPN or SKU
Exact lookup — 1 credit, no ranking involved
Describe a situation or a need
Natural language search, with hard bounds as filters
Browse categories and refine
Facets, backed by consistent normalised attributes
Ask an assistant in conversation
Natural language search, with post-retrieval verification against spec
Send photographs
Image search — a different mode again
Do all of the above
All three retrieval modes, routed by input shape
The mature answer for most product surfaces is not a choice. It is routing: exact lookup when there is an identifier, keyword when the query looks like a product name, semantic when it looks like a sentence, image when it is a photograph — with filters applied consistently across all of them and a verification pass on every result set.
Frequently asked questions
Is semantic search always better than keyword search?+−
No. For a shopper typing an exact product name, keyword matching is faster, cheaper and more predictable, and for a known identifier an exact lookup beats both. Semantic retrieval earns its cost when the request describes a need rather than an item. Route by the shape of the input rather than picking one approach for everything.
Can I run both and merge the results?+−
You can run both, but do not merge the scores. A term-weighting score and a cosine similarity are not on a shared scale, and averaging them produces a ranking that means nothing. Either route each query to one method by input shape, or retrieve from both and re-rank on your own named criteria — specification fit, review coverage, price position — which you can actually test.
How do I stop semantic search returning near misses?+−
Verify after retrieval. Apply hard constraints as filters before search, then check the returned spec against the shopper's stated requirement in your own code and drop candidates that fail. Also respect the sanity filter: when meta.count is zero, that is a genuine answer and the right response is to say so rather than show the closest available product.
Does natural language search remove the need for good product data?+−
The opposite. Semantic retrieval can find a product despite the shopper using different words, but it cannot confirm that the product is quiet unless a noise figure exists somewhere in the record. Retrieval finds candidates; fields prove them. Thin product data makes semantic search more confident and less correct, which is the worst combination.
Image product search is only useful when the result is more than a visual match. The stages from photo to structured candidates, and how to handle confidence and ambiguity.