From a product photo to structured candidates | simlir blog
From a product photo to structured candidates
Image product search is only useful when the result is more than a visual match. The stages from photo to structured candidates, and how to handle confidence and ambiguity.
Image search becomes useful when a visual match resolves into structured candidates and evidence. Credit: Generated for Simlir
The short answer
Image product search is most useful when the result is not only a visual match. A photograph should resolve into structured candidates an application can compare, explain and link back to a retailer — identifiers, specifications, review context and a dated price snapshot. A visual similarity score on its own answers “does this look like that?”. It does not answer “is it the same product, is it available near me, and what does it cost?” — which is what the shopper is actually asking.
When shoppers reach for an image
Image input is not a novelty feature. It is what people do when they have a product in front of them and no vocabulary for it. Four situations dominate:
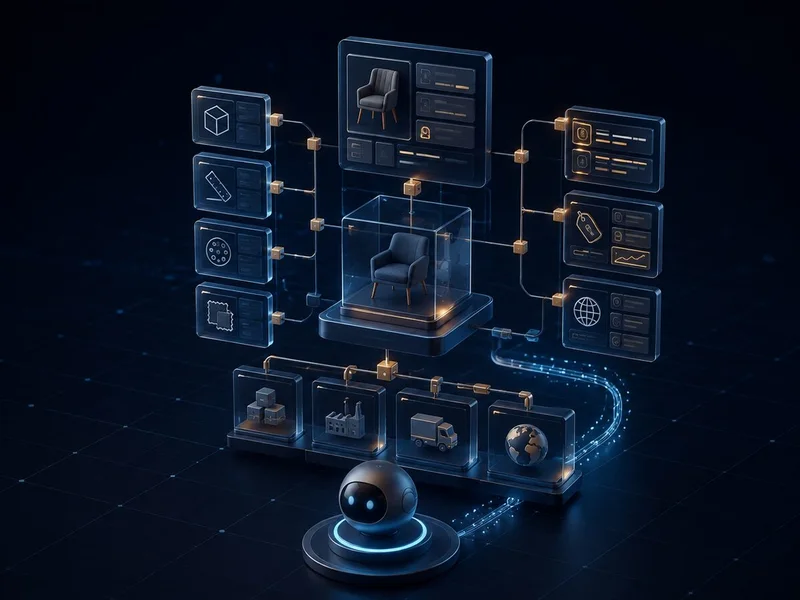
A seven-stage architecture for shopping assistant search: intent, retrieval, structured records, provenance, comparison, MCP or REST access, and failure testing.
They cannot name it. A component, a fitting, a fabric, a plant pot. The shopper knows exactly what they want and cannot type it.
They saw it somewhere. A screenshot from social media, a photo in a friend’s kitchen, a still from a video.
They have the physical object. A replacement filter, a cartridge, a bulb. The product is in their hand and the model number has worn off the label.
They want something similar but different. “Like this, but cheaper” or “like this, in blue” — a visual starting point plus a constraint.
Notice that only the second of these is really about visual similarity. The others are identification problems where the image is the input format, not the goal. That distinction shapes everything downstream: if your interface stops at “here are things that look alike”, you have answered a question only one of these four shoppers asked.
From image input to candidate retrieval
The simlir image endpoint takes a hosted HTTPS image URL and returns products in the same structured shape as text search, with a visual_similarity_score added. It costs 3 credits, and market is required.
Why a hosted URL rather than raw bytes. It keeps the request text-only, which matters in an agent workflow: with the MCP tool simlir_search_products_by_image, the model does not need to inspect the image itself before deciding to call the tool. It passes a URL along. That also means your application controls image hosting, retention and privacy — you decide what is stored, for how long, and under what policy.
Practically, this puts one step in front of your search call: get the shopper’s photo to a hosted HTTPS URL first. For a mobile app that usually means uploading to your own storage and passing the resulting URL. Plan for the upload latency in your interface, because it happens before any search work begins.
You can narrow the search at the same time. category, brand, min_price and max_price all apply to image search, which is how you serve the “like this, but under £50” case — visual input for the shape, filters for the constraint.
Confidence and ambiguity
Image search is inherently less certain than text search, and pretending otherwise is the main way these features lose trust. Three properties of the response deserve respect:
visual_similarity_score
Returned only by image search. It is a visual-match measure and is not comparable to the relevance_score returned by text search. Never blend the two into a single ranking number or sort a mixed list on whichever happens to be present.
limit is a ceiling
A post-search sanity filter removes obvious product-type mismatches, so an image request can return fewer results than asked for, or none. Read meta.count and treat an empty response as a legitimate answer.
Beyond the response itself, some ambiguity is inherent to photographs and no scoring model removes it:
Source of ambiguity
What happens
Reasonable response
Category is visually near-identical
Similar packaging across different products
Show several candidates; let the shopper disambiguate on specifications
Variant not visible
Capacity, size or pack quantity indistinguishable in the photo
Group candidates by model and surface the variant choice explicitly
Photo quality
Angle, lighting, occlusion, cropping
Lower confidence overall; prompt for a clearer photo rather than guessing
Product is not in the catalogue
Nearest neighbours returned, none correct
Show low-confidence framing, offer text search as an alternative
Wrong market
Product exists but not in the requested catalogue
Say which market was searched, rather than showing nothing without explanation
The last row is the one teams forget. An empty image result often means “not in this market’s catalogue”, not “this product does not exist”. Those are very different messages to a shopper.
Structured fields after the match
This is the point of the whole exercise. Once a photo has resolved to candidates, the shopper gets everything text search would have given them:
product object (abridged)
{
  "id": "a1b2c3d4-e5f6-7890-abcd-ef1234567890",
  "brand": "Optimum Nutrition",
  "category": "protein powder",
  "gtin": "5060245603478",
  "title": "Optimum Nutrition Gold Standard Whey Protein Powder",
  "product_description": "Premium whey protein powder with 24g protein per serving...",
  "key_selling_points": ["24g protein per serving", "5.5g BCAAs", "Informed Sport certified"],
  "spec": {
    "protein_per_serving": "24g",
    "servings": "29",
    "calories_per_serving": 120,
    "flavour": "Double Rich Chocolate"
  },
  "image_url": "https://images.optimumnutrition.co.uk/whey-front.jpg",
  "model_number": "GS100W-2270G-DRC",
  "retailer_sku": "ON-2270G-GB",
  "review_score": 4.8,
  "review_count": 20,
  "price": {
    "amount": 29.99,
    "currency": "GBP",
    "retailer": "Holland & Barrett",
    "as_of": "2026-04-07"
  },
  "links": {
    "retailer": "https://www.hollandandbarrett.com/shop/product/..."
  },
  "market": "gb",
  "relevance_score": 0.923
}
Which means the follow-up questions all become answerable without another round of image work:
“Is it cheaper anywhere else?” — the record carries a dated price snapshot with the retailer it was seen at.
“What size is it?” — spec, dimensions and weight, with units.
“Is it any good?” — review_score with its review_count.
“Where do I buy it?” — links.retailer, which may be null when there is no verified retailer product URL.
“Is this definitely the right one?” — gtin and model_number, which the shopper can check against the object in their hand.
That last one is underrated. When a shopper is holding the product, showing the identifier lets them verify the match themselves, which is far more convincing than any confidence score you could display.
The visual object is also useful in the interface: a short summary of what the hero image shows, labels, any clearly visible detected text, and dominant colours. It is derived from the product’s own hero image and is safe to show directly or pass to an agent. It is null when a row has not been visually enriched, so give that case a rendering.
Market and retailer context
Visual matching is global; buying is local. A product that looks identical in a photograph may be sold under a different model designation, in a different pack size, at a different price, in another country.
simlir requires market on image search and echoes it back on every product. Compare the value you sent against the value returned, and surface the market in your interface. “3 matches in the UK catalogue” is a materially more honest heading than “3 matches”.
Interface patterns for multiple candidates
Text search can defensibly show one strong answer. Image search rarely should.
Show a small set, not one result. Three to five candidates with visible distinguishing attributes lets the shopper resolve the ambiguity in a second, using knowledge you do not have.
Lead with what distinguishes them. If two candidates differ by capacity, put capacity on the card. A grid of near-identical photographs is the least useful way to present a visual match.
Show the shopper’s own image alongside. It makes comparison immediate and makes a wrong match obvious rather than authoritative.
Offer refinement, not just rejection. “None of these” should lead somewhere: a text query, a category filter, a prompt for a clearer photo.
Say what was searched. Market, and any filters you applied on the shopper’s behalf.
Design the empty state first. It will be seen more often than in text search, and it is where trust is won or lost.
Testing false matches
Standard relevance testing will not surface the failures that matter here, because it uses clean catalogue images. Build an evaluation set from photographs that look like the ones your users will actually send.
ScreenshotsCropped from social media and video, with overlaid text and compression artefacts.
Near-identical productsSame brand, different variant. The hardest and most commercially damaging case.
Products outside the catalogueConfirm the system degrades honestly rather than returning a confident wrong answer.
Products outside the marketCheck the message distinguishes “not here” from “does not exist”.
Non-product imagesPeople, scenery, documents. Confirm you return nothing rather than something.
Empty and short responsesVerify the interface handles a meta.count of zero without breaking.
Score two things separately: how often the correct product appears anywhere in the returned set, and how often it is ranked first. The gap between those numbers tells you whether to invest in ranking or in presentation. If recall is high but top-one accuracy is low, showing five candidates solves your problem far more cheaply than any model change.
Frequently asked questions
Can I send an image file instead of a URL?+−
The documented contract takes a hosted HTTPS image_url on both the REST endpoint and the MCP tool. In practice that means uploading the shopper's photo to your own storage first and passing the resulting URL. It is a deliberate design: it keeps agent tool calls text-only, and it leaves image retention and privacy policy in your hands rather than ours.
How does image search cost compare to text search?+−
Image search costs 3 credits against 2 for semantic text search. If your interface lets a shopper click into a candidate or return to it later, cache the product id from the result and re-fetch through /v1/product for 1 credit rather than repeating the image search.
Can I combine an image with a text query?+−
Not as a single blended query, but you can constrain an image search with category, brand, min_price and max_price, which covers the common 'like this, but cheaper' and 'like this, but from this brand' cases. For a genuinely different requirement, run a text search separately and present the two result sets as what they are rather than merging their scores.
What score counts as a good match?+−
There is no universal threshold, because it depends on your category and on the cost of being wrong. Set it empirically against your own evaluation set, and be aware that a threshold tuned on clean catalogue images will be too strict for real shopper photographs. In most interfaces, showing several candidates and letting the shopper choose beats tuning a threshold to show exactly one.
MCP suits tool use inside an agent workflow. REST suits direct service integration. A decision table, auth notes and an implementation checklist for choosing between them.